waybackmachinedownloader.org
Your site is still in the Wayback Machine.
Point it at a domain. Get the archived pages back as working HTML, CSS and assets. $12 for the whole domain, no page limit.
Last capture before the gap:
Five years with nothing. Everything after that date is gone unless somebody else kept it.
The example is theglobe.com, one of the first social networks, read from the Internet Archive’s own index. Most dead sites look like this: captured often, then not at all.
What a restore gives you back
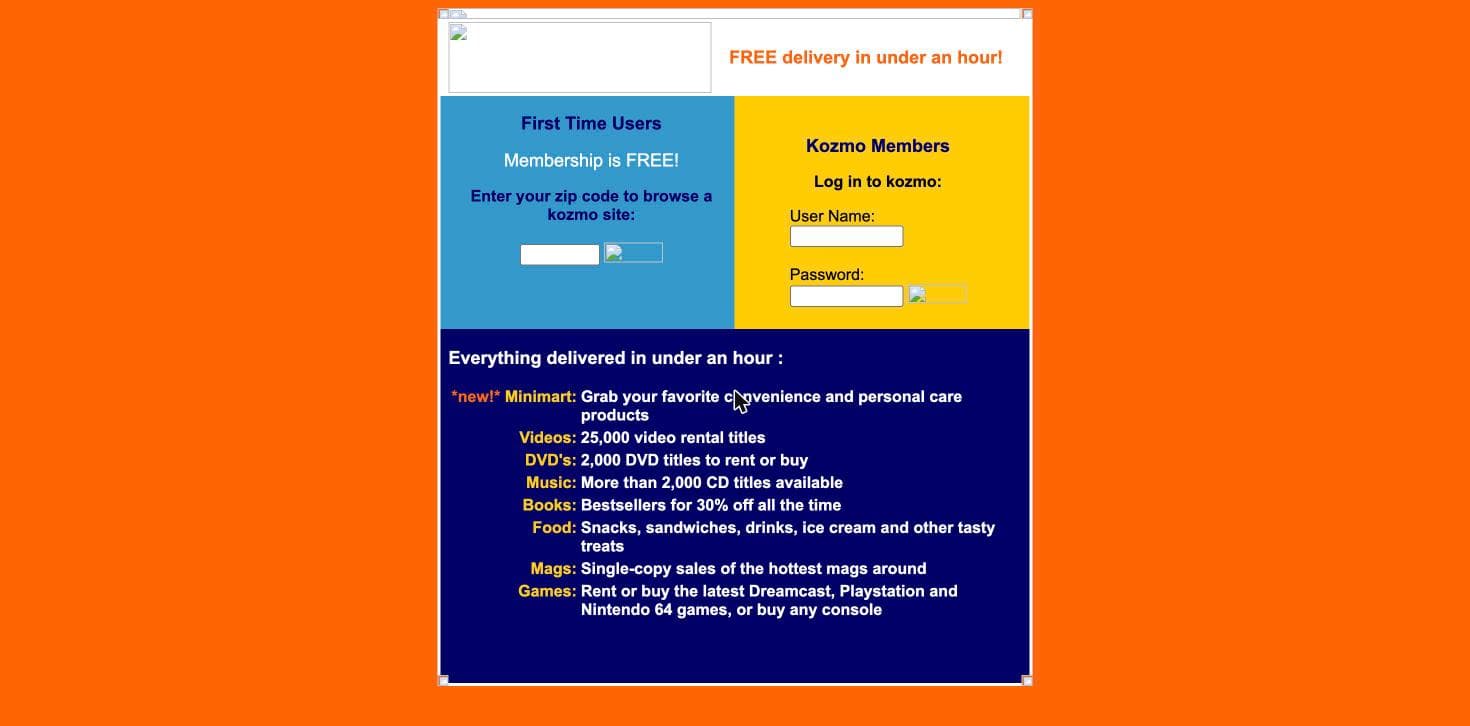
Kozmo promised delivery in under an hour and folded in 2001. The domain has been dark ever since. The Archive kept the site, so the recovered copy opens close to the original.
- DNS
- No record
- HTTP
- No response
- Live since
- 2001
Nothing answers on this domain. There is no page here to screenshot.
- Pages written
- 895
- Images
- 192
- Stylesheets
- 383
- Time
- 6m 35s
Five pages failed out of 900. The full example shows both restores with every number as it came out.
What works today and what is coming
Restore a site from the Wayback Machine Works today
Give it a domain and get every captured page back as working files. $12, no page limit. Ordering is manual for now, and you see the result before you pay.
Download a live website In development
Point it at a site that still answers and get the front end as files. This is being built now. The page covers the methods that work in the meantime.
Recover deleted YouTube videos In development
The hardest of the three, and also being built. The Archive usually holds the watch page and rarely the video file itself. The guide explains what survives a deletion.
How a restore works
Everything the Archive captured for your domain can come back as one working site.
- Read the indexEvery URL the Archive holds
- Fetch each captureAs recorded, no toolbar
- Rewrite the linksPoint at the local copy
- Write to diskOriginal folder structure
- You give it a domain. The site you want back, however long it has been gone.
- It reads the Archive’s index. Every URL the Wayback Machine holds a successful capture for, which for an old site can run to thousands.
- It fetches each page as it was captured, without the Archive’s own toolbar and URL rewriting baked into the HTML.
- It rewrites the links. Internal links point at the local copy, so the restored site browses offline instead of reaching back out to a site that no longer exists.
- You get the files. HTML, CSS, images and assets, in the directory structure the original site used.
When people restore a site from the Archive
The site is gone and there is no backup. The host shut down, the drive failed, or nobody renewed the account. The Archive is what survived.
You bought a domain and want what used to sit on it. The pages are in the Archive and you want them as files.
You need the old copy on record. A page said something, it changed, and you want the earlier version saved rather than left as a link that could rot.
You are rebuilding and want the original in front of you. Copy, structure and assets from the site as it was.
New to how any of this works? What the Wayback Machine is, and what it holds.
Archive.org and the Wayback Machine are not the same thing
Archive.org is the Internet Archive’s whole collection. It holds books, audio, video, software and web pages. The Wayback Machine is the web page part of it. Someone searching for an archive.org downloader who means old web pages is after the Wayback Machine.
Questions people ask
Can I download a whole domain, not just one page?
Yes. That is what this is for. You give it a domain and it works through every URL the Wayback Machine holds for that domain.
Will I get every page that ever existed on the site?
No. You get what the Wayback Machine captured. Pages it never snapshotted cannot be restored by any tool, and coverage varies a lot between sites.
Do the restored pages actually work?
Internal links are rewritten to point at the local copy, and the CSS and assets come with it, so the pages open and browse offline. The Internet Archive's own toolbar is stripped out.
What does it cost?
$12 for a whole domain, with no limit on the number of pages. Large sites take longer to run but they do not cost more.
Is it legal to download from the Wayback Machine?
Recovering a site you own or operate is ordinary. Republishing someone else's content, or rebuilding their site as your own, is a copyright question and the tool you used does not change the answer. The Internet Archive serves public pages; what you do with them afterwards is on you.
Is it safe to download from the Wayback Machine?
The files are whatever the site served at the time, so treat them the way you would treat any old code. Archived pages can carry outdated scripts and dead third-party embeds. Read what you get before you republish it, and never run an archived server-side script without reviewing it first.
Can you download videos from the Wayback Machine?
Rarely. The Archive captures the web page a video sits on, and the media stream itself almost never enters the archive. An archived watch page usually comes back with its title and description intact and a player that will not play.
How long does a restore take?
Longer than people expect. The Archive answers a single page request in about two seconds, so a 500 page site is roughly twenty minutes of work. Large sites run for hours.
Working out which archive to use in the first place? Compare the Wayback Machine against five alternatives. Trying to save a site that is still live? Four methods that actually work.